Do you rely on a Policy Decision Point (PDP) for authorization? Then congratulations — you’re one of the “lucky” ones experiencing a 200–300ms delay (and I am not considering some outliers that I have seen taking seconds) on every protected request.
And here’s the kicker: nobody believes you when you complain about it.
Authorization latency rarely shows up in metrics dashboards. It’s treated as the necessary evil, the tax you pay for security, the “well, what can you do?” of system architecture. So you accept it. Your users feel it (they just blame “the app” generally). Your infrastructure pays for it (blocked threads aren’t free). Your engineers work around it (adding complexity nobody asked for).
But what if I told you this doesn’t have to be the rule?
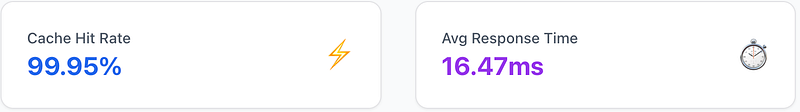
I just stress-tested our PDP deployed on AWS with 600 concurrent users — from my laptop. The outcome? 90ms total latency. 12ms engine execution. And that’s before optimization.
Let me show you what’s possible when you stop accepting slow authorization as inevitable.
The Math Nobody Does
Let’s say your team needs to access a resource multiple times a day. To grant access, you run two authorization checks:
- First check: User’s department and clearance (living in your HR system)
- Second check: Resource attributes (living in an external system — Microsoft Graph is a perfect example)
Each access attempt? 300–400ms of authorization overhead.
Now, what if we could reduce that to 60–90ms?
Here’s the math:
- 200 access requests per day
- Savings: ~250ms per request
- Daily gain: 50 seconds per user
Multiply this across multiple resources and multiple teams, and suddenly you’re buying back hours of productive time every single day.
But here’s what really hurts: most companies don’t even measure this. Authorization latency is the invisible tax — your users feel it, but they just think “the app is slow.” Your dashboards show fast API responses, but conveniently leave out the 300ms authorization tax added on top.
You’re paying for it in user frustration, infrastructure costs, and architectural compromises. You just don’t see an invoice.
Why Everyone’s Authorization Is Slow
Too many traps on the way, placed smartly to catch you off guard.
Trap 1: The Database Round-Trip Pattern
Relying solely on databases to fetch attributes for your policy engine is a recipe for slowness:
- Multiple queries per authorization decision
- Delays that compound under load
- In the cloud era, extra database load you have to pay for
Query user → Check roles → Fetch permissions → Verify resource → Check membership = 110ms minimum, 200–300ms under real load.
Trap 2: Caching the Wrong Thing
Here’s where most teams get it wrong: they cache the authorization decision itself.
❌ Bad caching: "Can Alice edit Document #42?" → Cache result
Problem: "I removed the user from the group, but they still have access!"
You end up building complex cache invalidation logic, dealing with stale permissions, and creating security holes. Plus, cache lookups aren’t free — Redis still adds 30–50ms.
The smart approach? Cache the attributes, not the decisions. And be smarter. Not all attributes are equal. Always target for the cache that rarely changes and for the frequent ones use smaller cache TTL. That will get you the best results.
✅ Good caching: User's department, clearance level, resource sensitivity
These change rarely (monthly, weekly at most)
Fresh decision every time, fast attribute lookups
This is what gets us to 12ms execution — we’re not re-fetching attributes from Graph or MySQL every time, but we’re always making fresh authorization decisions based on current policy logic.
Trap 3: The LLM Hype
“Let’s use AI for intelligent authorization decisions!”
Are you the type that has an LLM for everything? Then you’ve probably noticed that LLMs are:
- Slow (2–5 seconds per decision — seriously)
- Expensive ($0.002 per request adds up fast)
- Inconsistent (“Why did the AI deny access today? ¯\(ツ)/¯”)
And here’s the real kicker: you still need to fetch attributes to feed the LLM, so you’re adding DB delays + caching complexity + LLM latency on top. It’s the worst of all worlds.
Our contrarian take: Use AI to write the policy once, then execute it with fast, deterministic code forever. Get the intelligence without the runtime penalty.
The Key Insight Section
So what makes our approach different?
We cache attributes (user department, resource classification) because they’re stable — they change monthly or weekly, not per-request. This gives us a 99%+ cache hit rate.
But we never cache the authorization decision itself. Every request gets a fresh policy evaluation in 12ms based on:
- Current policy logic (can be updated instantly)
- Cached attributes (fast to fetch)
- Real-time context (current time, request metadata)
Result: Speed of caching + Correctness of real-time evaluation.
No stale permissions. No “but I revoked access!” bugs. No complex invalidation logic.
Just fast, correct authorization every single time.
Real Numbers from Production
This time, the setup is as close to a production system as possible. No localhost dockerized environments. No dummy data. No more laptop overheating (well, mostly).
Test Setup:
- AWS deployment — ECS Fargate (real cloud infrastructure)
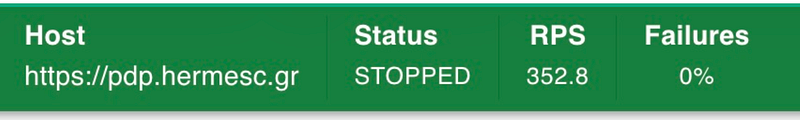
- Locust with 600 concurrent users for stress testing (could go higher, but the M4 chip has its limits)
- Complex policies requiring:
- User attributes from MySQL database
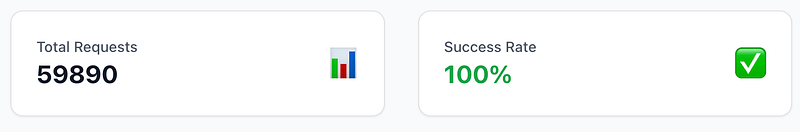
- Resource attributes straight from MS Graph API calls - Result: 352.8 RPS sustained, 0% failures
- And in just 3 minutes, we successfully served 60k requests

Performance Breakdown:
Total: ~90ms (unoptimized)
├─ Engine execution: 12ms
│ ├─ Policy evaluation: ~4ms
│ ├─ Attribute fetching (cached): ~6ms
│ └─ Decision rendering: ~2ms
└─ Network overhead: ~78ms
└─ Optimizable to ~30–40ms
And here’s a real sample from our audit logs showing the internal breakdown:
"timing": {
    "total_time_ms": 12.318138,
    "engine_time_ms": 1.172193,
    "opa_time_ms": 0.92067
}
Where:
- total_time: Request/response time inside the PDP engine
- engine_time: Time to fetch policy metadata and connector attributes from database
- opa_time: Time the policy engine took to return a decision
The Key Insight
The engine execution is 12ms. The remaining 78ms is network overhead — and network is solvable with standard optimizations:
- Regional AWS deployment (reduce geographic latency)
- HTTP/2 with connection reuse
- CDN edge endpoints
Our target: ~60ms total end-to-end latency
How Does This Compare?
╔═════════════════════════╦════════════╗
║        Approach         ║  Latency   ║
╠═════════════════════════╬════════════╣
║ Traditional DB          ║ 200-300 ms ║
║ Cached solutions        ║ 50-150 ms  ║
║ External services       ║ 200-500 ms ║
║ This (unoptimized)      ║ 90ms       ║
║ This (optimized target) ║ 60ms       ║
╚═════════════════════════╩════════════╝
Already 2–3x faster than industry standard — before optimization.
Why Laptop Testing Matters
Running 600 concurrent users on a laptop isn’t a limitation — it’s a feature. It proves:
- No exotic infrastructure required — You don’t need a $50K/month AWS cluster
- Thread-limited, not architecture-limited — Horizontal scaling is trivial (just add instances)
- The bottleneck is network, not the engine — And network problems are solvable
When the M4 chip becomes the constraint, you know the software architecture is sound.
What Makes This Approach Different (Beyond Just Speed)
In our business, a great product is one you don’t see or feel. It lives in the dark, constantly fulfilling its purpose, adding virtually unnoticeable overhead. But speed alone isn’t the innovation — it’s what speed enables when combined with the right architecture.
1. No Data Migration Required (Because ETL Jobs Are Where Dreams Go to Die)
Traditional authorization systems want you to:
- Export your data from where it lives
- Transform it into their special proprietary format
- Import it into their database
- Keep syncing it forever (and deal with the inevitable sync failures at 3 AM)
This is exhausting. And expensive. And your data is never fresh.
Our approach? We connect directly to your source systems. MySQL? Sure. MS Graph? No problem. MongoDB? Why not. REST APIs? Obviously.
We fetch attributes on-demand. No duplication. No sync jobs. No stale data. Your data stays in your systems, in your tenant. We just ask for what we need, when we need it. And because we’re fast (remember that 12ms engine?), this actually works.
Think of it like this: Would you rather photocopy your entire address book every day, or just look up the number when you need to make a call? Exactly.
2. Policies in Plain English, Not Klingon
Traditional policy engines make you learn specialized languages. Rego. Cedar. XACML. These sound like prescription medications, not programming languages. “Ask your doctor if XACML is right for you.”
You need experts. You need training. You need weeks of testing because one wrong character breaks everything. It’s like learning Latin just to read a menu.
Our approach? Write your policy like you’re explaining it to a colleague:
“Users in Engineering with Secret clearance can access Confidential documents during business hours.”
That’s it. No angle brackets. No JSON schemas. No syntax errors.
AI takes your plain English and generates the optimized policy code. Once. Then it’s done. You get auto-generated unit tests to verify it works. You get client SDKs in Python, JavaScript, Java, Go ready to use.
Your security team writes what they want. AI handles the implementation. Developers get working code. Everyone’s happy. Well, except the XACML consultants.
3. Deployment in Days, Not “Let Me Check the Calendar for Q3”
Traditional authorization infrastructure deployment:
- Months of integration meetings
- Complex deployment pipelines that break in creative ways
- Coordination across seven teams who all have conflicting priorities
- Extensive testing, rollback planning, disaster recovery documentation
By the time you’re done, the requirements have changed twice and Bob from security has retired.
Our approach? We deploy in your AWS or Azure tenant. You pick the connectors you need (ignore the ones you don’t). From “here are our requirements” to “authorization is live in production” takes days.
Not quarters. Days.
And because it runs in your infrastructure, you own it. No vendor lock-in. No “sorry, our API is having issues” excuses. It’s yours.
4. Real-Time Collaboration That Actually Works
Now that we’ve covered the foundation, let’s talk about what sub-100ms authorization enables when you’re fetching fresh data:
Google Docs-style collaboration where permissions are constantly checked:
- Every file access: “Can this user view?” (60ms, feels instant)
- Every save: “Can they modify?” (no noticeable delay)
- Every share action: “Can they grant access to others?” (immediate feedback)
At 250ms per check with stale cached data, this is either slow or wrong (pick your poison). At 60ms with fresh attributes from source systems, it’s fast AND correct. Novel concept, right?
5. Row-Level Security Without the Usual Compromises
Want to check authorization on every row in a database query? Traditional wisdom says “you can’t, it’s too slow.”
Traditional approach: Pre-compute permissions, denormalize into tables, accept that data is hours or days old, pray nothing goes wrong.
Our approach: Just check it. For real. Every row. Every time.
Because when your authorization engine is 12ms and fetches fresh attributes, you can actually do it right instead of making architectural compromises nobody wanted.
6. Audit Trails That Don’t Make Compliance Teams Cry
Every authorization decision gets logged with complete context:
- Who requested access
- What resource and what action
- Which attributes were evaluated (department: Engineering, clearance: Secret, fetched fresh from HR system)
- Which policy rule applied
- Why it was allowed or denied
- Complete timing breakdown for the nerds (hi!)
At 250ms with copied data, your compliance officer worries about gaps and staleness. “But is this the CURRENT state?”
At 60ms with direct queries to source systems, your auditors see a perfect, real-time trail with fresh data. They might even smile. Probably not, but maybe.
The Complete Picture
It’s not just that we’re fast. It’s that we’re fast while:
- Querying live data from YOUR source systems (no copying)
- Using policies written in plain English (no Klingon)
- Running in YOUR infrastructure (no vendor lock-in)
- Deployed in days (not geological epochs)
- Maintaining perfect audit trails (compliance-friendly)
- Never duplicating or stale-ing your data (always fresh)
When authorization is this fast AND this flexible, it stops being the thing you worry about and becomes the thing you just use. Like it should be.
The Divine Collaboration (Or: What We Actually Call This Thing)
Throughout this article, I’ve been calling it “our authorization system” or “the PDP engine.” Professional. Technical. Adequately boring.
Time for the real introduction.
Meet Metis.
But here’s the thing — Metis doesn’t work alone. In Greek mythology, when Hermes, the swift messenger of the gods, encountered Metis, the Titaness of wisdom and deep thought, their collaboration created something unprecedented: intelligence that could think with divine foresight yet act with lightning speed.
Sound familiar?
In our modern realm, this same convergence has emerged. Hermes represents the speed and connectivity our digital world demands — the messenger that delivers decisions instantly across systems. Metis embodies the profound intelligence needed to solve complex authorization challenges — the wisdom that thinks once, perfectly.
The Metis Philosophy
Our Metis platform channels this divine collaboration: AI wisdom that crafts perfect authorization policies combined with Hermes-like execution speed that delivers decisions in 12 milliseconds.
“Wisdom that thinks once perfectly, then executes forever with divine speed.”
Where others force you to choose between thinking (slow AI real-time decisions) or speed (oversimplified rules), Metis transcends this false choice. We use AI to think once — deeply, carefully, correctly — generating the perfect policy. Then we execute that wisdom forever with the speed of a divine messenger.
No compromise. No trade-offs. Just the best of both worlds.
Why This Matters Beyond Mythology
The name isn’t just marketing (though we do think it sounds cool). It represents the core architectural decision that makes everything else possible:
Metis (Wisdom) does the hard thinking once:
- Understands your natural language policy requirements
- Generates optimized, correct policy code
- Creates comprehensive test suites
- Produces ready-to-use client SDKs
Hermes (Speed) delivers the results forever:
- 12ms policy execution
- 352.8 RPS sustained under load
- Direct connections to your data sources
- Deployed in your infrastructure
Think once with wisdom. Execute forever with speed. That’s the divine collaboration.
Conclusion
Authorization doesn’t have to be the performance bottleneck everyone accepts as inevitable. With the right architecture — AI for wisdom, optimized execution for speed, and direct data connections instead of copying — you can have sub-100ms decisions that are both fast and correct.
Measure your authorization latency today. You might be surprised at what you find.
What’s your authorization latency? Do you even know? 🤔
Member discussion: